AI Chat v2 API Integration Guide
AI Chat v2 API (/aichat2/conversations) is the next-generation conversation interface and a comprehensive upgraded version of AI Chat API. Building on v1's simplicity and hosted multi-turn conversations, it expands with:
- Multimodal user input: Directly send text + image + file blocks through the structured
messagefield, without first attaching them indirectly throughreferences. - Agent-based tool calling: Includes a built-in set of tools for web search, web page fetching, file reading, and more, and can mount user-authorized MCP servers (Google Drive, Notion, Slack, GitHub, etc.). The model can autonomously call tools across multiple rounds within a single request to complete complex tasks.
- Structured streaming events: Use
accept: text/event-streamorapplication/x-ndjsonto receive token-by-token events such astext_delta,tool_use,tool_result,thinking,citation,card, andartifact, making it easy to render them separately by corresponding type in the frontend. - Interruptible / resumable: When the model needs users to provide additional information, it emits an
ask_user_questionevent and pauses. On the next call, simply fill in the answer throughtool_resultsto continue. - New CRUD actions: Complete
retrieve/retrieve_batch/update/deletethrough theactionfield on the same endpoint, without requiring an additional conversation management API. - Continuously updated model list: By default, it integrates contemporary models such as GPT-5.4, Claude Opus 4.8, Claude Sonnet 4.6, Gemini 3.1 Pro, GLM 5.1, DeepSeek V4, Kimi K3, and more.
At the request body level, it is fully backward compatible with v1: simply send model + question (+ optional stateful / id / references / preset) to receive a {answer, id} JSON response equivalent to v1. Therefore, migrating from /aichat/conversations does not require rewriting the client; you only need to change the path to /aichat2/conversations.
If you are currently using
/aichat/conversations, the old interface will remain available, and you can migrate at your own pace.
¶ Application Process
To use the AI Chat v2 API, first obtain your API Token from the 灵蛇AI Console and keep it for later use.
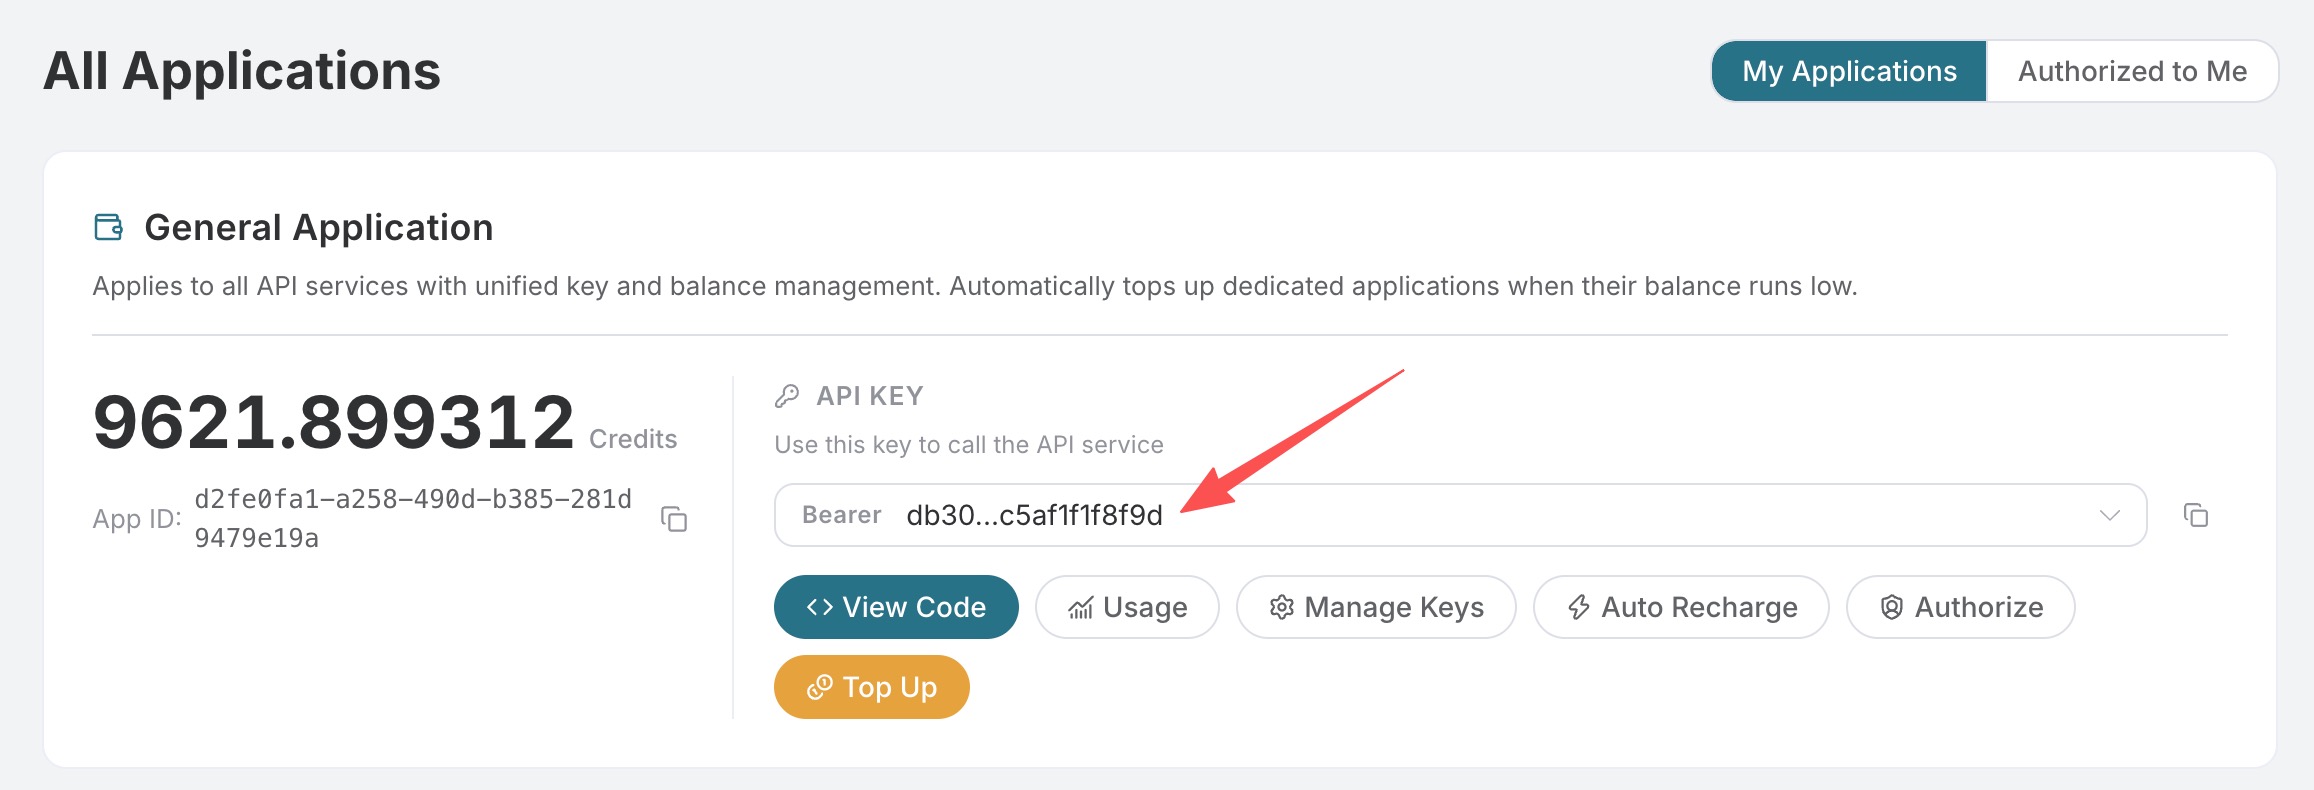
If you have not logged in or registered yet, you will be automatically redirected to the login page, where you will be invited to register and log in. After completion, you will automatically return to the current page.
One API Token can call all platform services; there is no need to apply separately for each service. Your first application includes free credits for a free trial; when credits are insufficient, you can top up your general balance in the Console.
📘 Full documentation: AI Chat v2 API →
¶ Basic Usage
The simplest usage is exactly the same as v1: send model + question and receive {answer, id}.
CURL example:
curl -X POST 'https://api.opensnake.cloud/aichat2/conversations' \
  -H 'accept: application/json' \
  -H 'authorization: Bearer {token}' \
  -H 'content-type: application/json' \
  -d '{
    "model": "gpt-5.4",
    "question": "用一句话介绍下 AceDataCloud。"
  }'
Response:
{
  "answer": "AceDataCloud 是一个聚合主流 AI 模型与多模态服务的统一 API 平台,开发者通过一个密钥即可调用 GPT、Claude、Gemini、Midjourney、Suno、Veo 等多家服务。",
  "id": "f2f4b3e8-0c0a-4d3a-aaa2-7ff80c0a1c44"
}
Python example:
import requests

url = "https://api.opensnake.cloud/aichat2/conversations"

headers = {
    "accept": "application/json",
    "authorization": "Bearer {token}",
    "content-type": "application/json",
}

payload = {
    "model": "gpt-5.4",
    "question": "用一句话介绍下 AceDataCloud。",
}

response = requests.post(url, json=payload, headers=headers)
print(response.json())
Available model values can be viewed directly in the dropdown in the Try panel on the right. Common categories include:
- OpenAI:
gpt-5.4-mini,gpt-5.4-nano,gpt-5.2-pro,gpt-5.1-all,gpt-5-all,gpt-4.1,gpt-4o,gpt-4o-image,o3,o4-mini, etc. - Anthropic:
claude-opus-4-8,claude-opus-4-7,claude-opus-4-6,claude-opus-4-5-20251101,claude-sonnet-4-6,claude-sonnet-4-5-20250929,claude-haiku-4-5-20251001, etc. - Google:
gemini-3.1-pro-preview,gemini-3.1-pro-preview,gemini-3.1-flash-image,gemini-3.1-pro-preview,gemini-2.5-flash-lite, etc. - xAI:
grok-4, etc. - DeepSeek:
deepseek-v4-pro,deepseek-v4.1-flash,deepseek-v4-flash,deepseek-v3.2-exp,deepseek-r1-0528, etc. - Moonshot:
kimi-k3.1-pro,kimi-k3,kimi-k2.6,kimi-k2.5, etc. - Zhipu:
glm-5.3,glm-5.2,glm-5.1,glm-5,glm-5-turbo,glm-4.7,glm-4.5v, etc.
For specific billing rules, see the Pricing card on the service page.
¶ Multi-turn Conversations
As with v1, send stateful: true to enable conversation storage. The API will return an id; simply include the id in subsequent requests to continue the conversation, without maintaining the messages history yourself.
First request:
curl -X POST 'https://api.opensnake.cloud/aichat2/conversations' \
  -H 'accept: application/json' \
  -H 'authorization: Bearer {token}' \
  -H 'content-type: application/json' \
  -d '{
    "model": "gpt-5.4",
    "stateful": true,
    "question": "记住一个数字:42。"
  }'
Response:
{
  "answer": "好的,我已经记住了 42。需要我用它做什么吗?",
  "id": "f2f4b3e8-0c0a-4d3a-aaa2-7ff80c0a1c44"
}
Second request, include the same id:
curl -X POST 'https://api.opensnake.cloud/aichat2/conversations' \
  -H 'accept: application/json' \
  -H 'authorization: Bearer {token}' \
  -H 'content-type: application/json' \
  -d '{
    "model": "gpt-5.4",
    "stateful": true,
    "id": "f2f4b3e8-0c0a-4d3a-aaa2-7ff80c0a1c44",
    "question": "我刚才让你记住的数字是多少?"
  }'
{
  "answer": "你让我记住的数字是 42。",
  "id": "f2f4b3e8-0c0a-4d3a-aaa2-7ff80c0a1c44"
}
statefuldefaults totrue; omitting it is equivalent to explicitly passingtrue. Settingstateful: falseskips loading previous conversation history; this does not mean that the result of the current turn will not be saved, nor does it apply to tool workflows that need to continue after being paused.
¶ Long Conversations and Original Text Preservation
Context compression only organizes the content sent to the model in the current turn and does not replace saved chat records. Complete saved messages can still be read through action: retrieve; explicit editing or deletion of conversations still takes effect as requested.
The model can search for and read paginated historical original text within the current conversation. When continuing to revise an article, cite numbers, or prepare for publication, the corresponding original text should be read; summaries cannot be used in place of the main text. This capability does not automatically restore messages that were already lost in older versions.
If context organization fails, retain the conversation ID and check the error event; the service will not overwrite the original text with an empty summary. Tool operations completed before the failure may still be valid, so query their results first to avoid duplicate generation or duplicate publishing. When a single conversation reaches the storage limit, an explicit error will be returned; existing saved records will not be trimmed to free up space. You can export the required content and then start a new conversation.
¶ Streaming Responses
v2 supports two streaming formats, selected according to the accept header:
| Scenario | accept |
Data Format |
|---|---|---|
| Web frontend / EventSource | text/event-stream |
data: {json}\n\n, with the last line data: [DONE]\n\n |
| Server / CLI / Node streaming parsing | application/x-ndjson |
One JSON object per line |
| Streaming not required | application/json (default) |
Returns {answer, id} in a single response |
¶ NDJSON Example
import json
import requests

url = "https://api.opensnake.cloud/aichat2/conversations"

headers = {
    "accept": "application/x-ndjson",
    "authorization": "Bearer {token}",
    "content-type": "application/json",
}

payload = {
    "model": "gpt-5.4",
    "stateful": True,
    "question": "用三句话介绍杭州。",
}

with requests.post(url, json=payload, headers=headers, stream=True) as resp:
    answer = ""
    for line in resp.iter_lines():
        if not line:
            continue
        event = json.loads(line)
        if event.get("type") == "text_delta":
            # 与 v1 兼容:增量片段同时通过 delta_answer 字段提供
            answer += event["content"]
            print(event["delta_answer"], end="", flush=True)
        elif event.get("type") == "done":
            print()
            print("usage =", event.get("usage"))
Each NDJSON line is a structured event, the most common being text_delta:
{"type":"text_delta","content":"杭","delta_answer":"杭","id":"f2f4b3e8-..."}
{"type":"text_delta","content":"州","delta_answer":"州","id":"f2f4b3e8-..."}
{"type":"text_delta","content":"是","delta_answer":"是","id":"f2f4b3e8-..."}
...
{"type":"done","conversation_id":"f2f4b3e8-...","usage":{"prompt_tokens":21,"completion_tokens":58,"total_tokens":79},"terminal_reason":"natural_stop"}
¶ SSE Example
The browser-side EventSource does not support custom request bodies. It is recommended to use fetch + manually parse by splitting on \n\n:
const resp = await fetch("https://api.opensnake.cloud/aichat2/conversations", {
  method: "POST",
  headers: {
    accept: "text/event-stream",
    authorization: "Bearer {token}",
    "content-type": "application/json",
  },
  body: JSON.stringify({
    model: "gpt-5.4",
    stateful: true,
    question: "用三句话介绍杭州。",
  }),
});

const reader = resp.body.getReader();
const decoder = new TextDecoder();
let buffer = "";
while (true) {
  const { value, done } = await reader.read();
  if (done) break;
  buffer += decoder.decode(value, { stream: true });
  const blocks = buffer.split("\n\n");
  buffer = blocks.pop() ?? "";
  for (const block of blocks) {
    const dataLine = block.split("\n").find((l) => l.startsWith("data: "));
    if (!dataLine) continue;
    const payload = dataLine.slice(6);
    if (payload === "[DONE]") return;
    const event = JSON.parse(payload);
    if (event.type === "text_delta") process.stdout.write(event.content);
  }
}
¶ Streaming Event Types
type |
Meaning |
|---|---|
text_delta |
Incremental text fragment of the assistant's response. content contains the new content; for v1 compatibility, the same event also carries delta_answer (equal to content) and id. |
thinking |
The model's reasoning process (appears only when the selected model exposes reasoning). |
tool_use |
The model decides to call a tool. The event carries tool_id, tool_name, and input. |
tool_result |
Tool execution result, paired with the preceding tool_use through tool_id; is_error indicates whether it failed. |
card |
Structured cards produced by tools (such as images or link previews), suitable for direct rendering. |
citation |
Source URL used to supplement citations for the corresponding text fragment. |
ask_user_question |
Issued when the model needs the user to provide additional information. The conversation enters the awaiting_user_input state; see Resuming Paused Conversations below. |
artifact |
Independent artifacts generated by the model (such as code blocks or documents), which can be saved or downloaded. |
system_message |
System prompt information (not user or assistant content), used only for UI prompts. |
compact |
The model context has been organized; saved original messages remain unchanged, and the client does not need to delete chat records. |
error |
An error occurred in the current turn; message describes the error. |
done |
The final conversation record for the current turn was saved successfully. It carries usage (including prompt_tokens / completion_tokens / total_tokens) and terminal_reason; whether the task is complete must still be determined by the termination reason. |
For clients that only care about the final answer, concatenating the content of all text_delta events is equivalent to answer in application/json mode. |
¶ Multimodal Input
If the user input contains images or files, pass message (an array) instead of question. Each array element is a content block:
{
  "model": "gpt-5.4",
  "stateful": true,
  "message": [
    { "type": "text", "text": "这张图片里有几只猫?" },
    { "type": "image_url", "image_url": { "url": "https://cdn.acedata.cloud/cats.jpg" } }
  ]
}
Supported block types:
text— Plain text, requires thetextfield.image_url— Image, requiresimage_url.url.file_url— File (PDF, CSV, TXT, etc.), requiresfile_url.url.
¶ Relationship with v1 references
To maintain compatibility with older clients, v2 still recognizes the references: ["https://...", ...] field:
- If the URL suffix is
jpg / jpeg / png / gif / bmp / webp / svg / heic / heif, it is automatically converted into animage_urlblock; - Other extensions are converted into
file_urlblocks; - If
questionis also provided, it is prepended as atextblock.
Therefore, if you only want to migrate from v1 and do not want to change the request body, simply change the path to /aichat2/conversations, and the original references usage will continue to work as usual.
If you need finer control (for example, placing multiple images between text, or when order is important), directly use the message array.
¶ Tool Calls and MCP
The core enhancement of v2 is that the model can autonomously call tools to complete multi-step tasks. This is enabled by default, and no additional configuration is required from the client in the request. Common scenarios:
- User asks, “Help me search for recent new exhibitions in Shanghai” → The model calls the built-in web search → Organizes the results into an answer.
- User asks, “Read this PDF and then write a summary” → The model calls file_read → Writes a summary.
- The user has authorized Google Drive / GitHub / Notion, etc. in Connections → The model can call the corresponding MCP tools to read and write their data.
In NDJSON / SSE streams, tool calls are represented through two types of events, tool_use and tool_result, for example:
{"type":"tool_use","tool_id":"toolu_01ABCDEF","tool_name":"web_search","input":{"query":"上海 2026 春季展览"},"id":"f2f4b3e8-..."}
{"type":"tool_result","tool_id":"toolu_01ABCDEF","output":"...","is_error":false,"id":"f2f4b3e8-..."}
{"type":"text_delta","content":"目前","delta_answer":"目前","id":"f2f4b3e8-..."}
{"type":"text_delta","content":"上海","delta_answer":"上海","id":"f2f4b3e8-..."}
...
If you do not want to display tool call details in the frontend, simply ignore event types such as tool_use / tool_result / card / citation; the model’s final output will still stream through text_delta.
max_turns can limit the maximum number of rounds in which the model can call tools itself in this request, with a range of 1–500 and a default of 500 when omitted. Setting it small (for example, max_turns: 1) can force a single response and disallow any tool calls.
¶ Asynchronous Execution and Unattended Authorization
If your call comes from an alert Webhook, CI/CD, monitoring system, or another background task, you can set async: true to make the API immediately return a task ID while continuing execution in the background:
{
  "model": "gpt-5.5",
  "async": true,
  "question": "我的服务报警了,用个人微信通知微信群「AceDataCloud团队」……"
}
Response example:
{
  "task_id": "f2f4b3e8-0c0a-4d3a-aaa2-7ff80c0a1c44",
  "conversation_id": "f2f4b3e8-0c0a-4d3a-aaa2-7ff80c0a1c44",
  "id": "f2f4b3e8-0c0a-4d3a-aaa2-7ff80c0a1c44",
  "status": "queued"
}
Afterward, you can use action: retrieve + id to query the conversation result; you can also provide callback_url, and after the task is completed, the platform will POST { status, answer, usage, error } to your callback address. callback_url must use http / https, and must not directly specify localhost or a private IP literal address.
There is usually no one available to click confirmation for background tasks. If you want certain Skills or MCP Servers to perform actions such as sending, publishing, or writing in unattended mode, explicitly pass a pre-authorization list in the request body:
{
  "model": "gpt-5.5",
  "async": true,
  "allowed_skills": ["acedatacloud/personal-wechat"],
  "allowed_mcp_servers": [],
  "question": "我的服务报警了,用个人微信通知微信群「AceDataCloud团队」……"
}
The values in allowed_skills are the slugs of connected Skills; the values in allowed_mcp_servers are the slugs of connected MCP Servers. Skills / MCP Servers not included in the pre-authorization list can still only preview, dry-run, or refuse to perform write operations in unattended mode.
If more granular control is needed, you can also use the equivalent unattended_policy object:
{
  "unattended_policy": {
    "allowed_skills": ["acedatacloud/personal-wechat"],
    "allowed_mcp_servers": [],
    "expires_at": 1790000000
  }
}
Pre-authorization is these two lists themselves: an empty list means no capabilities are authorized, with no additional switch field required.
Note: Pre-authorization only means “this request allows these capabilities to skip manual confirmation in unattended mode.” The specific Skill must still support --unattended-confirm or the corresponding security mechanism; otherwise, it will continue to dry-run and will not directly perform write operations.
¶ Resuming Paused Conversations
Some tools cause the model to “ask the user a follow-up question.” At this point, the model emits an ask_user_question event, and the conversation is frozen in the awaiting_user_input state:
{
  "type": "ask_user_question",
  "tool_id": "toolu_01XYZW",
  "tool_name": "ask_user_question",
  "question": "你希望生成的报告是中文还是英文?",
  "options": ["中文", "英文"],
  "id": "f2f4b3e8-..."
}
In the frontend, render this event as a card for the user to select an answer, then initiate the next request using the same id and fill the answer back through tool_results:
curl -X POST 'https://api.opensnake.cloud/aichat2/conversations' \
  -H 'accept: text/event-stream' \
  -H 'authorization: Bearer {token}' \
  -H 'content-type: application/json' \
  -d '{
    "model": "gpt-5.4",
    "stateful": true,
    "id": "f2f4b3e8-0c0a-4d3a-aaa2-7ff80c0a1c44",
    "tool_results": [
      {
        "tool_use_id": "toolu_01XYZW",
        "output": "Chinese"
      }
    ]
  }'
The tool_use_id in the request body must exactly match the tool_id at the time of suspension; otherwise, a 400 response will be returned. When tool_results is present in the request, question / message / references will all be ignored.
If the user decides to abandon this question, simply pass a new question / message, and the platform will automatically mark the suspended tool call as "user skipped".
¶ Conversation Management (CRUD)
v2 provides lightweight conversation management on the same endpoint through the action field, without requiring an additional API.
¶ action: retrieve —— Retrieve a conversation
curl -X POST 'https://api.opensnake.cloud/aichat2/conversations' \
  -H 'accept: application/json' \
  -H 'authorization: Bearer {token}' \
  -H 'content-type: application/json' \
  -d '{
    "action": "retrieve",
    "id": "f2f4b3e8-0c0a-4d3a-aaa2-7ff80c0a1c44"
  }'
Returns the complete conversation document (including messages history, model, title, tools_used, and more).
¶ action: retrieve_batch —— List conversation summaries
{
  "action": "retrieve_batch",
  "model_group": "chatgpt",
  "limit": 20,
  "offset": 0
}
Returns { items: [...], total }. Summaries do not include messages, making them suitable for sidebar lists; if the user opens a conversation, use action: retrieve to retrieve its complete messages separately.
Optional filtering parameters: user_id, application_id, model_group, model.
¶ action: update —— Change the title or rewrite history
{
  "action": "update",
  "id": "f2f4b3e8-0c0a-4d3a-aaa2-7ff80c0a1c44",
  "title": "Hangzhou Travel Plan"
}
messages can also be passed, but the server will perform strict schema validation (it must be in the collapsed ToolUseContent form), and a 400 response will be returned if it does not comply. Generally, it is only recommended for changing the title.
¶ action: delete —— Delete a conversation
{
  "action": "delete",
  "id": "f2f4b3e8-0c0a-4d3a-aaa2-7ff80c0a1c44"
}
Returns { id, success: true }. It cannot be recovered after deletion; please confirm before calling it.
¶ Smooth Migration from v1
If you are already using /aichat/conversations, migrating to v2 requires almost no code changes:
- Change the URL from
https://api.opensnake.cloud/aichat/conversationstohttps://api.opensnake.cloud/aichat2/conversations. - If you previously passed v1 model names (such as
gpt-3.5,gpt-4-browsing, etc.), it is recommended to upgrade to contemporary models when switching to v2 (such asgpt-5.4,claude-opus-4-8,gemini-3.1-pro-preview, etc.). - The fields in the NDJSON stream remain backward compatible: each
text_deltaevent still includesdelta_answerandid, so clients that originally parseddelta_answerline by line do not need to be changed.
After migration, you can enable v2's new capabilities as needed (multimodal message, SSE, tool calls, action CRUD) and proceed at your own pace.
¶ Error Handling
Error responses follow a unified format:
{
  "error": {
    "code": "chat_error",
    "message": "model service returned an error"
  },
  "trace_id": "2cf86e86-22a4-46e1-ac2f-032c0f2a4e89"
}
Common errors:
400 bad_request: Missing required fields, mismatchedtool_use_id, invalidmessagesschema, etc.401 invalid_token: Theauthorizationheader is incorrect.404 not_found: The conversation corresponding to theiddoes not exist when usingaction: retrieve / update / delete.413 conversation_storage_limit: The conversation exceeds the storage limit, and existing saved records were not overwritten.429 too_many_requests: The rate limit was triggered.503 context_compaction_failed: Context consolidation failed; existing records are retained.500 conversation_persist_failed: Final saving for this round failed; received text does not mean the final record was saved successfully. Please query by conversation ID.500 chat_error: The service is temporarily unavailable, or no content was generated in this round (no charges will be incurred).
In streaming responses, errors are emitted as {"type":"error","message":"..."} events, after which the stream ends. [DONE] only indicates that transmission has ended; when there is an error, it cannot be considered successful, and a successful done event will not be sent.
¶ Conclusion
While remaining backward compatible with v1, the AI Chat v2 API upgrades conversations from "single-turn / multi-turn Q&A" to "agent-oriented observable conversations": multimodal input, tool calls, pausable / resumable operation, structured streaming events, and built-in CRUD. It is recommended that new integrations use v2 directly; existing v1 integrations can migrate smoothly in stages. If you have any questions, please feel free to contact our technical support team.